Today
Pilots that never pass security review
With Bilions
Models run inside your environment, which security can approve
Private LLMs, RAG systems, and production AI workflows with evaluation baked in. For teams where data sovereignty and audit trails aren’t optional.
The questions legal and security teams ask, answered before the first sprint.
Most AI pilots stall between demo and production. Legal and security teams ask where the data goes, nobody can measure answer quality, and results change after a model update.
Pilots that never pass security review
Models run inside your environment, which security can approve
No reliable way to tell whether answers are correct
An evaluation suite built from your real questions
Cost and quality shift every time the model changes
Eval gates block any change that lowers quality
Documents, tickets and records stay in your cloud.
Answers grounded in your documents, with sources shown.
Test suites built from your real questions and expected answers.
Models that run inside your cloud account or data center.
Monitoring, access controls and usage reporting.
Changes that lower quality are blocked before release.
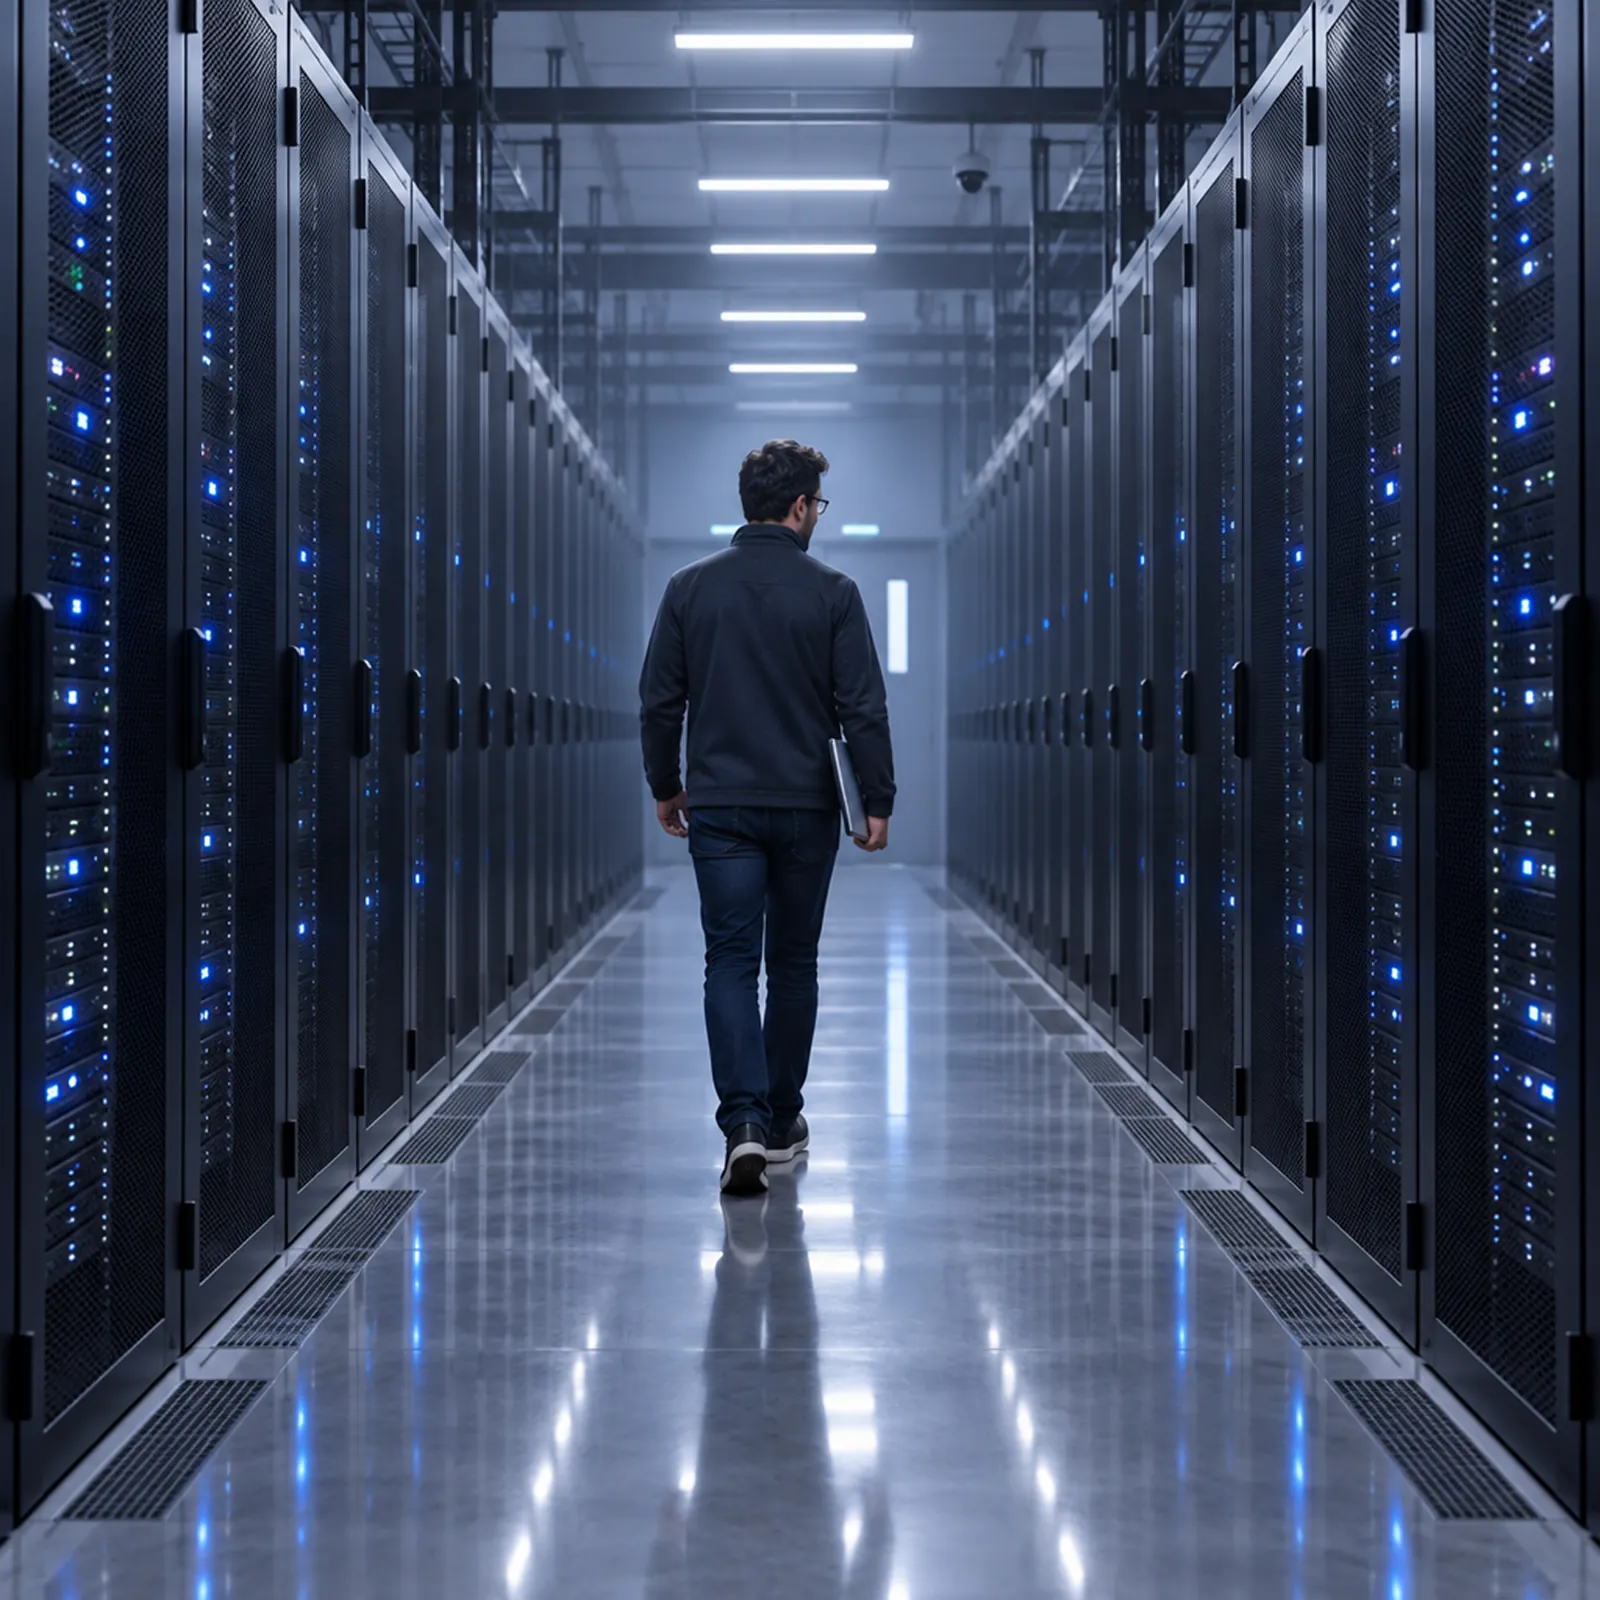
Healthcare, insurance and finance teams that cannot share data externally.
Exploring AI with the controls procurement expects.
Adding AI features that customers can trust.
Bilions developed a custom document processing tool for the mortgage industry, leveraging advanced OCR technology. This solution improved document pro…
Not answered here? Ask an engineer
Yes. We deploy private models and retrieval inside your cloud account or data center, so your data stays within your boundary.
We build an evaluation suite from your real questions and expected answers, then run it on every change. A change that lowers the score does not ship.
OpenAI, Anthropic and open models such as Llama. We choose based on your data rules, cost and accuracy needs.
Your first call is with a senior engineer from our team.